Language Model Basics
A Token Count Is Not a Word Count
Measure text with the tokenizer used by the model instead of assuming that words, characters and tokens have a fixed one-to-one relationship.

Clear thinking about intelligent tools.
Measure text with the tokenizer used by the model instead of assuming that words, characters and tokens have a fixed one-to-one relationship.
Evaluate a quantized AI model as a separate deployment choice, measuring memory, task quality and compatibility instead of relying on the bit-width label.
Temperature changes how a language model samples tokens. It can affect variation, but lowering it does not verify facts or guarantee the same answer everywhere.
Understand why embedding similarity can retrieve related sentences that disagree, and test negation, numbers and conditions before using a score as evidence.
Preserve the date, page and supporting passage behind an AI-assisted search result so another reader can check what you actually reviewed.
Compare AI workflow speed from user request to usable result, including retrieval, validation, retries and review rather than model response time alone.
Ask how synthetic data was generated and tested before treating it as anonymous, and evaluate privacy separately from usefulness.
Read an AI model card for intended uses, evaluation conditions and limitations, then identify what still needs testing in your own application.
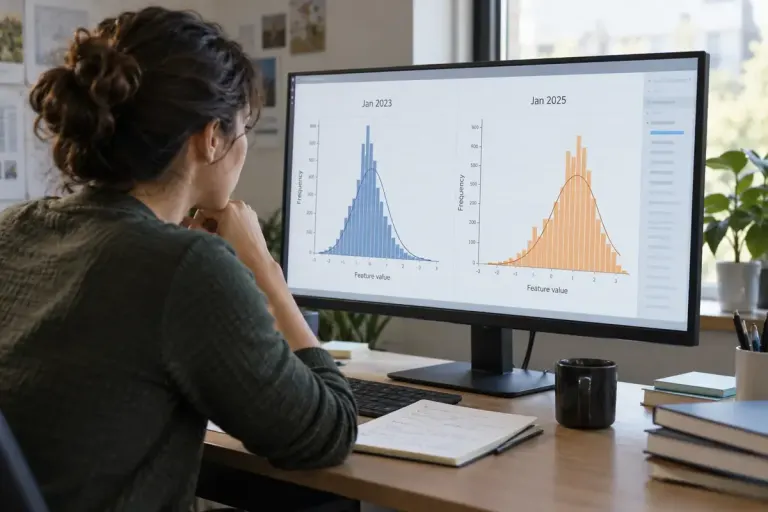
Understand how changing input data can affect a deployed AI system, and distinguish a drift alert from evidence that its predictions have become worse.