Machine Learning Practice
Stratified Sampling Preserves Labels, Not Every Important Difference
Stratification can preserve class proportions in a train-test split. It does not automatically balance every feature or prevent data leakage.

Clear thinking about intelligent tools.
Stratification can preserve class proportions in a train-test split. It does not automatically balance every feature or prevent data leakage.
Macro and micro averaging answer different questions about classifier performance. Use a small example to see why class balance matters.
Record the environment and sources of randomness alongside a seed when comparing machine-learning experiments.
A model’s context window includes more than your document. Budget for instructions, history, tools, and the answer you want it to produce.
Read a confusion matrix by checking its axes and label order, then use a small worked example to find errors hidden by an overall accuracy figure.
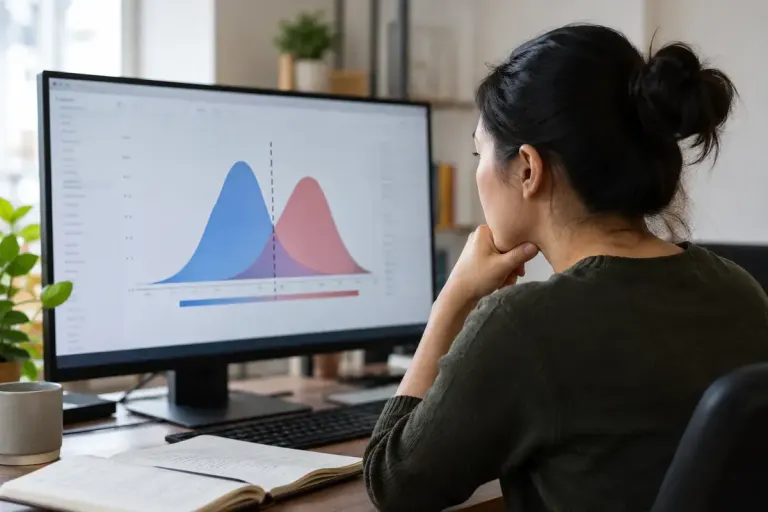
See how a classifier’s decision threshold changes false alarms and missed cases, using a small worked example and a fixed evaluation set.
Document chunk boundaries can separate an answer from its condition. Test retrieval with real questions before choosing a chunk size for an AI system.
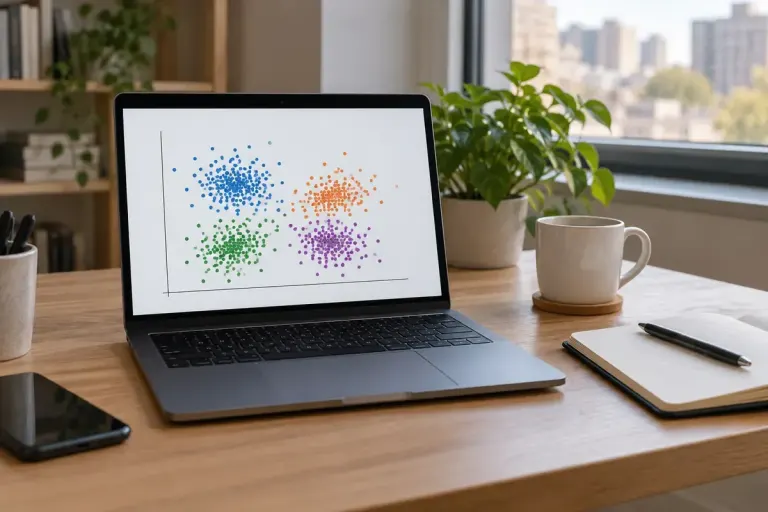
Understand an embedding as a learned numerical representation without assuming each coordinate has a tidy human-readable meaning.
Distinguish training from inference so questions about AI cost, data use and model changes are directed at the right process.