Class weights change the learning penalty, not the population you measure
Class weights alter a classifier’s training penalties. Use a small numerical example to see why they do not change the real-world frequency of a class.
Class weights alter a classifier’s training penalties. Use a small numerical example to see why they do not change the real-world frequency of a class.
Read permutation importance cautiously when model inputs carry overlapping information, and distinguish a small score drop from proof that a feature is useless.

A decision tree’s maximum depth limits its layers of questions. Compare shallow and deeper trees using held-out data rather than training fit alone.

Compare cosine similarity and dot products with a small vector example, then check how normalisation affects an AI retrieval system.

Decide how a one-hot encoder should handle unseen categories, and test the distinction between an unknown value, missing data and a dropped reference category.

Chronological validation asks whether a forecasting model could have made its prediction using only information available at that moment.

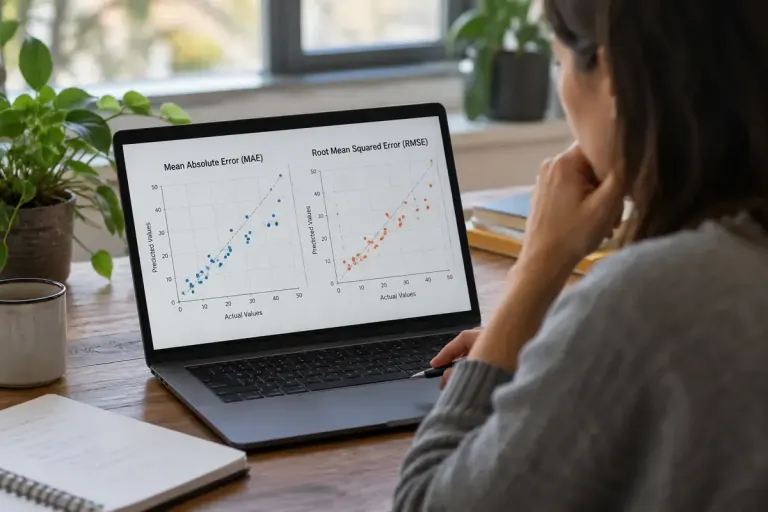
Compare MAE and RMSE with a small prediction-error example, then choose evaluation metrics that reflect the cost of large mistakes in your application.

Split related observations by group when testing generalisation, and check that subjects, sessions or source documents do not leak across partitions.

Define the positive class before reading precision and recall, and use a small confusion example to see what each measure counts.