
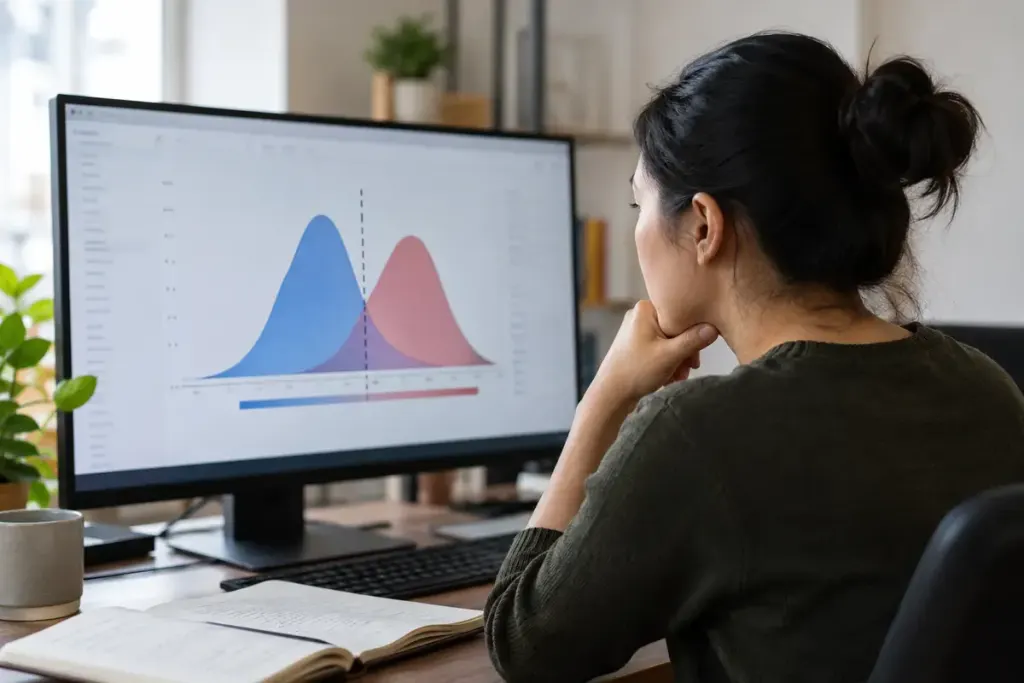
A classifier can produce the same scores and still make different decisions after one setting changes. The threshold determines which scores are treated as positive. Changing it is a policy choice about action, not a fresh demonstration that the model has learned more.
For an illustrative document-routing tool, suppose three documents score 0.82, 0.61 and 0.35 for needing specialist review. With a rule that sends scores of at least 0.50 to review, the first two are selected. At a threshold of 0.75, only the first is selected.
Count the consequences
To judge either setting, you need checked labels for the documents. If the middle document genuinely needed review, raising the threshold misses it. If it did not, the higher threshold removes an unnecessary referral. The scores alone do not tell you which outcome occurred.
Google’s classification threshold lesson explains the trade-off between positive and negative decisions. Raising a threshold generally reduces the number of predicted positives; that can reduce false positives while increasing false negatives. The exact counts depend on the evaluation data and the decision rule.
State how equality is handled too. “Above 0.75” and “at least 0.75” differ for a score of exactly 0.75. A small implementation detail can matter at scale.
Choose with a separate evaluation process
Compare candidate thresholds on an appropriate validation set, then assess the selected approach on data not used to tune it. Examine the costs of missed cases and unnecessary reviews, along with the team’s capacity to handle the resulting queue.
Record the threshold, model version, dataset period and counts of each outcome. A single accuracy percentage can conceal a substantial change in who gets flagged.
After deployment, monitor whether the population and error pattern change. Do not silently adjust the threshold to make a dashboard look better. The people relying on the decisions need to understand what changed and which trade-off the new setting represents.