
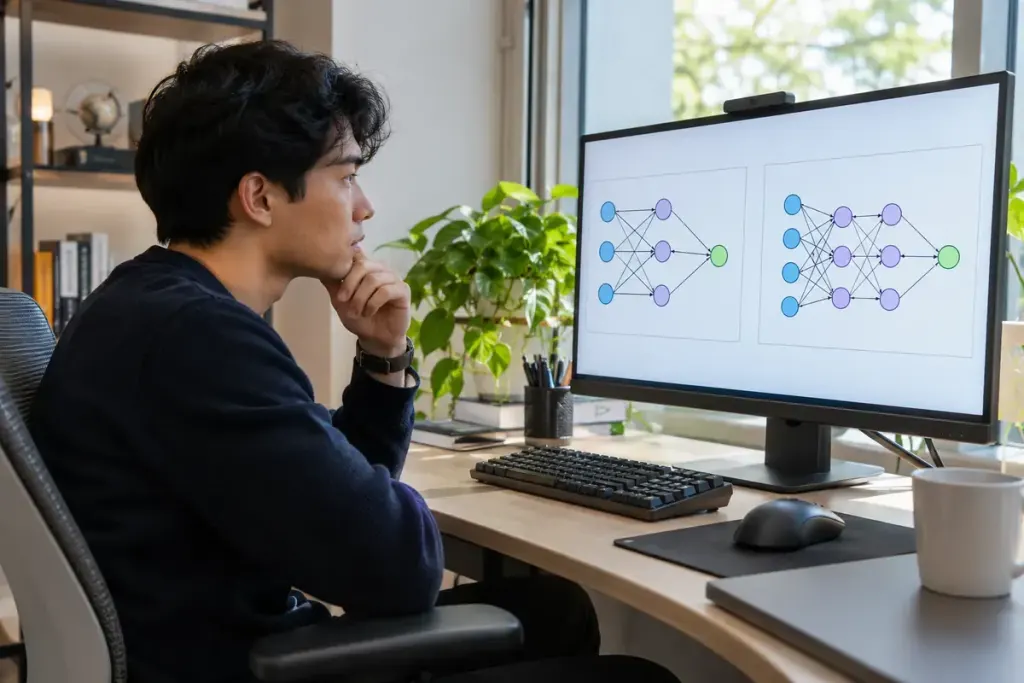
A smaller model can be trained using the outputs of a larger one. This is the central idea behind knowledge distillation: a teacher supplies a learning signal to a student. The result is not a literal copy of the teacher compressed into fewer bytes.
Research on knowledge distillation in sequence generation describes teacher predictions as training targets. In classification, probability distributions can convey more than the single highest-scoring class. Different distillation methods use different targets and objectives, so the term covers more than one recipe.
A small probability example
Imagine a fictional classifier choosing among three categories. The teacher assigns probabilities of 0.60, 0.35 and 0.05. A hard label keeps only the winning category. A soft target retains information that the teacher considered the second category much more plausible than the third.
That extra information may be useful for training, but it is still the teacher’s behaviour. If the teacher has a systematic error, agreement with it is not automatically evidence of truth.
Define what the student must preserve
A deployment team might want lower memory use, faster responses or a model suitable for a particular device. Specify those requirements alongside task quality. “Smaller” is an engineering property; “good enough” needs evaluation on the intended use.
Google Research’s study of distillation behaviour reports that teacher and student predictions can remain substantially different, even when simple expectations suggest the student should match. The paper is a reason to measure the result rather than assuming the teacher’s abilities transferred intact.
- Compare task performance on held-out examples relevant to deployment.
- Inspect important failure cases, including areas where the teacher is unreliable.
- Measure the actual latency and resource use in the target environment.
Keep the training signal and the evaluation evidence separate in the project record. A student can be useful without matching every teacher output, and close imitation can still be unsuitable for the application. Distillation is a training strategy, not a certificate of equivalent capability.